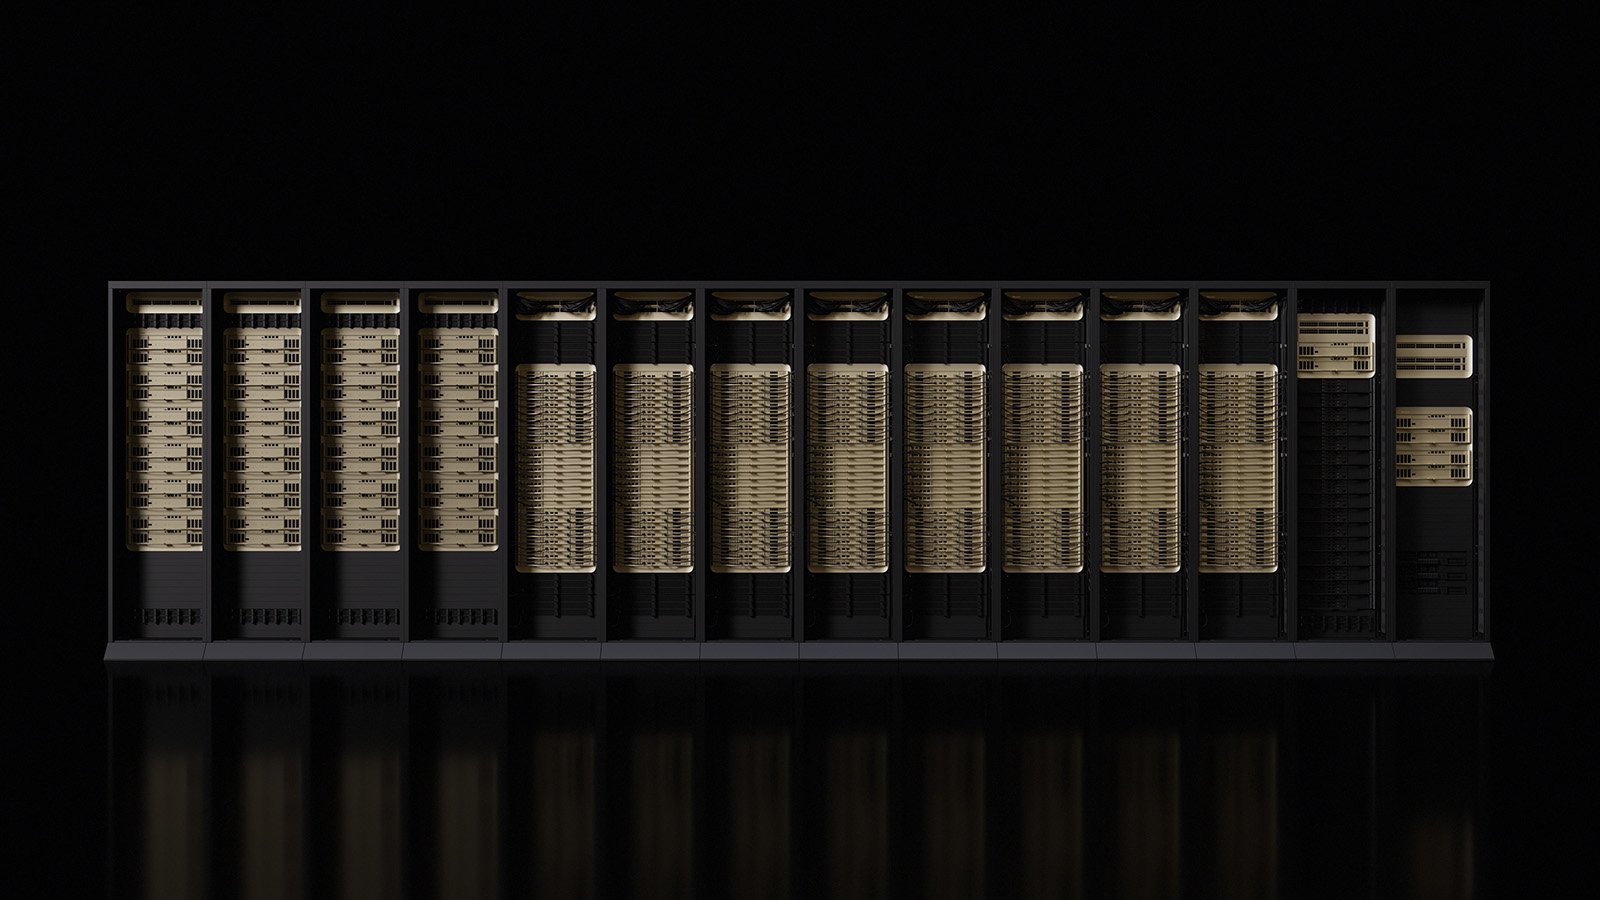
AI GPU Cloud. Reserved capacity
Predictable economics.
GPU clusters and on-demand instances, optimized for distributed AI and HPC workloads. Multi-year contracts on B300, B200, GB300, and H200 infrastructure — anchored by direct GPU ownership.
Built for every workload.
Southeast Asia's AI compute demand is outpacing local supply, with limited sovereign and dedicated-capacity options. Cosmic's facilities are built to close that gap — in-country deployment, data residency, and dedicated clusters where hyperscalers typically don't reach.
Train LLMs
Multi-GPU clusters with Slurm scheduling and InfiniBand networking for fast, distributed training.
Deploy AI agents
Prototype and run agentic AI with containerized environments, NIM APIs, and GPU acceleration.
Operate ML pipelines
GPU-accelerated environments with observability, versioning, and automation via CLI, Terraform, and GitOps.
Run CUDA & HPC workloads
Direct GPU access for CUDA development, GPU kernel testing, and high-performance scientific computing.
Train faster. Scale smarter.
Next-generation NVIDIA infrastructure with liquid-cooled efficiency and full support for distributed training and inference.
NVIDIA B300
Cosmic's flagship Blackwell Ultra platform — purpose-built for the largest training jobs and the most demanding low-latency inference workloads.

Built for enterprise
users.
Multi-year fixed-term contracts with dedicated capacity and predictable allocation. Designed for AI labs, media platforms, and sovereign workloads that demand stability over years, not minutes.
- ✓Dedicated GPU pools — never shared, never preempted
- ✓Flexible term structures for committed deployments
- ✓Regional availability in Malaysia and Indonesia
- ✓In-country contracting available where local entities exists
- ✓Pre-deployment burn-in and acceptance testing
- ✓Quarterly business reviews and dedicated solutions architecture
Non-blocking fabric
InfiniBand, Spectrum-X, and RoCE options for demanding training jobs.
High-performance storage
Parallel filesystems, NVMe checkpoint tiers, S3-compatible object storage.
Enterprise SLA
99.9% uptime SLA, 24/7 support, mission-critical operations and credit remedies.
Optimized for AI developers.
CUDA-ready environments, Jupyter notebooks, and NIM toolkits — all included out of the box. With Slurm integration, observability, and hybrid cloud connectivity, you get GPU power without setup overhead.
The tools you already use.
AI Workbench
On-demand or reserved instances for AI workloads, ready to deploy.
NIM Inference APIs
Deploy AI development environments instantly with NVIDIA NIM.
Observability & Monitoring
Track GPU usage, job performance, and costs with built-in observability tools.
The latest NVIDIA GPUs, available on-
demand or as reserved clusters.
Training LLMs
B300 / GB300 multi-node clusters with InfiniBand
Running inference
B200 instances for fast deployment
Research & CUDA dev
Single-node configs for experimentation
Talk to us about a multi-
year reserved contract.
Capacity is allocated quarter-by-quarter. Contact our team to discuss upcoming availability.