
AI compute
infrastructure at scale.
Cosmic Computing owns and operates high-density GPU infrastructure globally and provides unified multi-model API access — from dedicated training clusters to on-demand inference, in one platform.


Trusted by leading OEMs, supply chain partners and global enterprise players
Combined power capacity procured, deployed, and managed
Combined data center and compute infrastructure experience
OEM relationships across the GPU supply chain
Deploying NVIDIA Blackwell generation GPU clusters
AI compute infrastructure,
end to end.
We operate end to end across infrastructure, distribution, and optimization, supported by direct GPU ownership, regional allocation capabilities, and unified access to 100+ frontier AI models.

GPU NeoCloud
Long-term enterprise GPU leasing for AI training and inference.
- Multi-year contracts
- Dedicated capacity
- Reserved deployments

ModelLink
100+ AI models. One API. One bill.
- Unified multi-model access
- Intelligent routing, 99.9% uptime
- Real-time cost metering
Dedicated infrastructure for frontier training and production inference.
Foundation Model Training
Multi-thousand GPU clusters with NVLink fabric and RDMA networking, built for stable long-running training workloads.
Large-Scale Inference
Low-latency, high-throughput inference infrastructure with autoscaling and distributed workload management.
Sovereign & Regional AI
In-country AI infrastructure designed to support regional deployment, data residency, and compliance requirements. Delivering a Tier IV–certified sovereign AI compute hub in Kuala Lumpur, Malaysia — 2N+1 fault-tolerant architecture, 99.995% facility SLA.
Generative Media & Video
GPU infrastructure optimized for video generation, diffusion training, and high-throughput media workloads.
Reinforcement Learning & Agents
Managed RL plumbing so research teams can focus on experiments.
HPC & Scientific Computing
Traditional HPC and cloud-native workloads supported through enterprise-grade infrastructure and tier III or higher data centers.
ModelLink is the unified multi-model API layer from Cosmic Computing.
One interface to access language, image, video, and audio models from OpenAI, Anthropic, Google Gemini, BytePlus, Meta (Llama), Stability AI, and more. Intelligent routing and cross-provider load balancing deliver 99.9% availability. Real-time metering, analytics, cost dashboards, and enterprise-grade SLAs included.
No per-provider integration. One bill. One dashboard.

Unified access
One API key for 100+ models. No per-provider integration.

Intelligent routing
Automatic failover and load distribution. Zero-downtime model switching.

Cost optimization
Real-time per-token metering, volume discounts, BYOK support for select providers. Customers report 40–50% lower API costs from smart routing alone.

Full observability
Dashboards for usage, latency, error rates, and cost allocation.

Developer-ready
OpenAPI spec. Python and JavaScript SDKs available. More languages coming.

Creative workflows
Text-to-image, image-to-video, text-to-speech, and agentic workflow tooling for multimodal content production.
SUPPORTED MODELS
Access to general-purpose large language models alongside specialized models for focused tasks such as text-to-video generation, across leading providers including OpenAI, Anthropic, Google Gemini, BytePlus, Meta, and Stability AI.
USE CASES
- ·AI application development — Build with model fallback and cost controls.
- ·Enterprise AI integration — Unified governance, billing, and compliance across providers.
- ·Multimodal content creation — Generate images, video, audio, and text from a single API.
- ·Model evaluation — Compare performance and cost across providers.
- ·Workflow automation — Embed AI with consistent API semantics.
Proven across live and in-progress deployments.
Global livestreaming platform
Fastest path to live deployment, supporting immediate AI compute demand.
Construction-focused robotics company
Active mid-stage deployment, supporting AI training and inference workloads.
Regional AI token factory
Broader, multi-party partnership spanning infrastructure, compute access, and ecosystem collaboration.
Compliance built into every deployment.

Institutional compliance
KYC, AML, EUC and sanctions screening built into every deployment. Engaged top-tier international legal and compliance counsel to secure multi-layered regulatory certifications ahead of regional rollout.

Sovereign-ready
Data residency support at the deployment layer, with local operating-company contracting structures where available — including jurisdictions offering fiscal incentive status for qualifying digital infrastructure investment.
Built by operators.
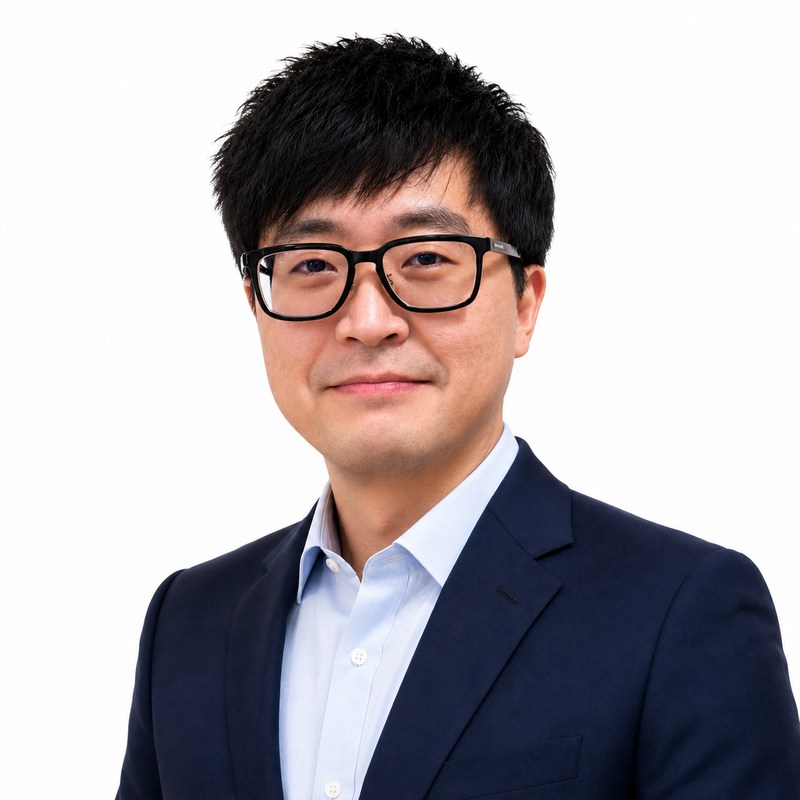
Eric Chen
Founder & CEO
Managed operations for 150MW+ of active data center facilities and directed physical construction execution for high-density compute environments. Generated $10M+ in critical hardware procurement, securing transformers and power distribution equipment.
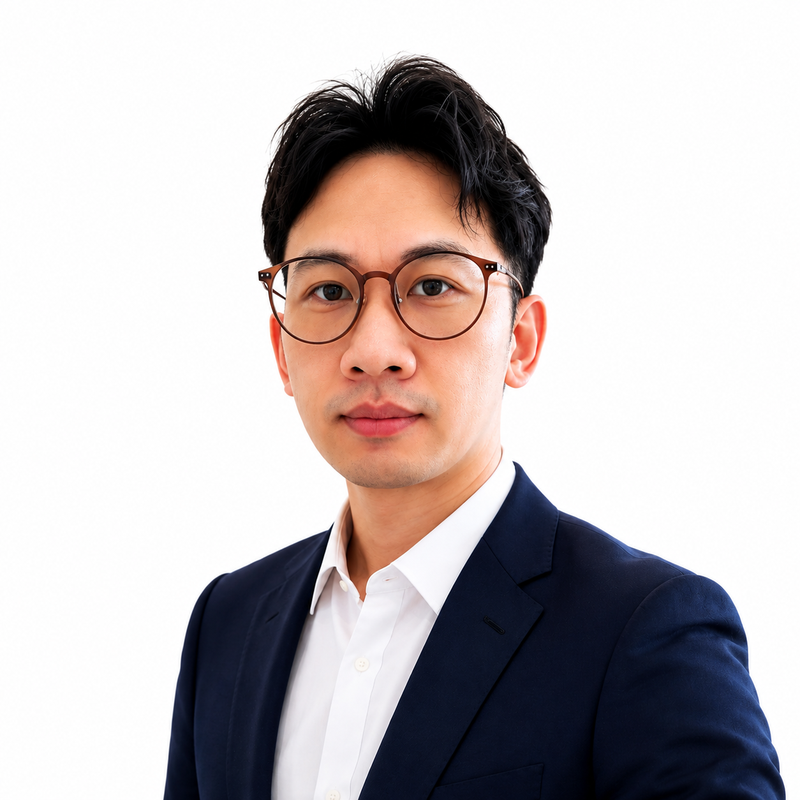
David Zhang
CTO
Directed a 130MW footprint managing 39,000 active compute nodes with a 24-person team at 99.97% fleet availability. Now designing Cosmic's GPU compute fabric, using automated edge telemetry to extend hardware lifespans by up to 24 months.
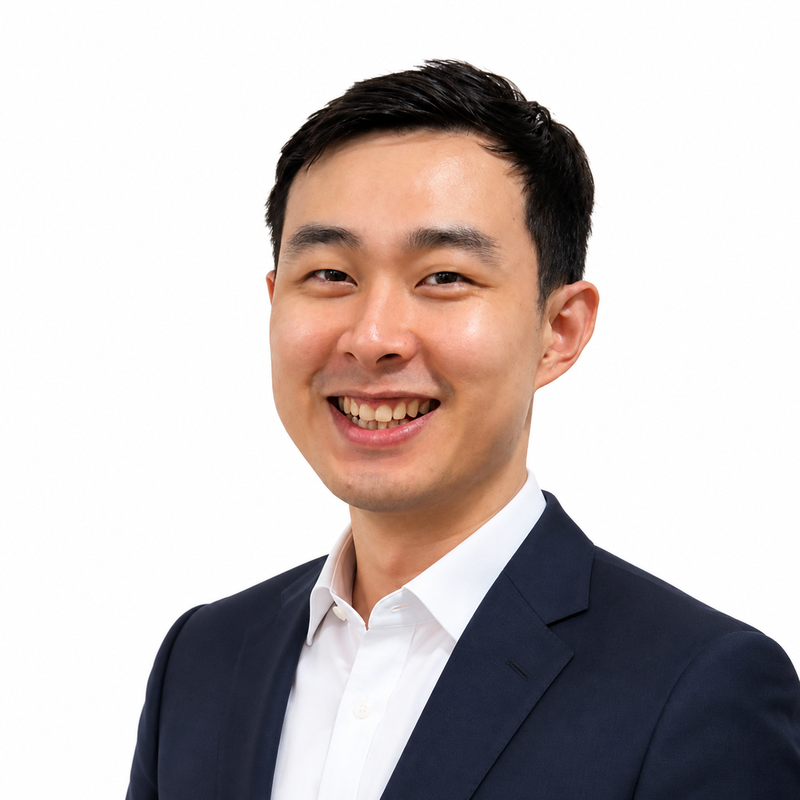
Yibo Huang
COO
Scaled go-to-market operations across marketplace and SaaS companies, from seed stage through Series A, as well as pre-IPO tech companies. Managed teams across APAC to grow customers and partnerships, building operational frameworks for customer engagement.
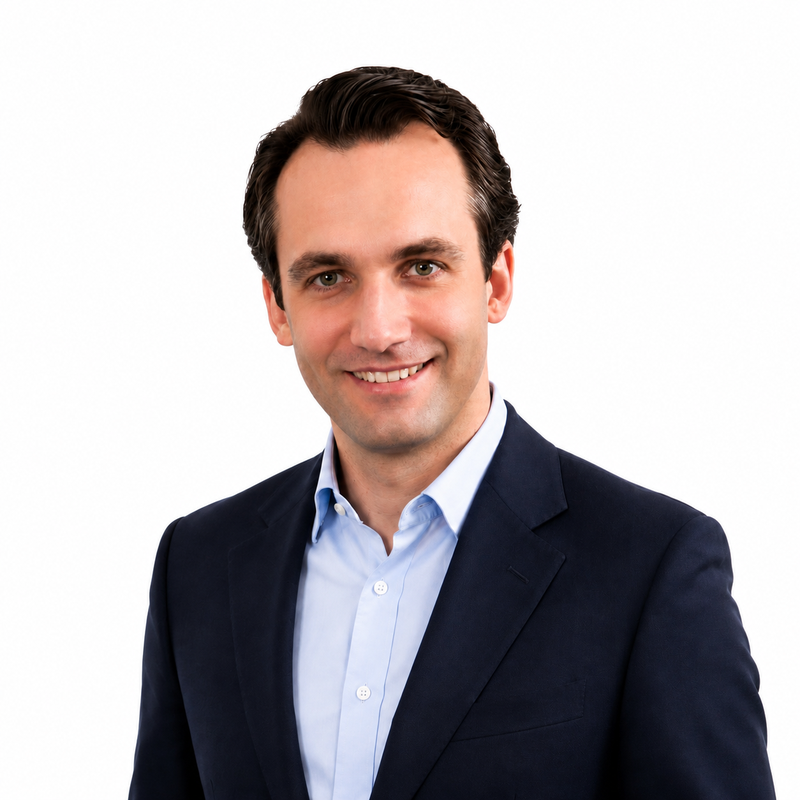
Oscar Prat van Thiel
CSO
Background in finance and institutional management, aligning Cosmic's infrastructure rollouts with sovereign priorities and securing partnerships across Europe, Asia, and emerging markets. Extensive experience navigating public-private alliances.
Where we operate.
Kuala Lumpur, Malaysia
Tier IV–certified sovereign AI compute hub, operated under Vertex Services (Malaysia) Sdn. Bhd.
Jakarta, Indonesia
Tier III facility.
Reserve dedicated AI compute capacity, or start using the unified model API — all through a single platform.
From single-node experiments to large-scale training runs, and from one-off API calls to production multimodal pipelines. Multi-year reserved contracts, on-demand burst capacity, and unified model access — anchored by direct GPU ownership.